Contents
I. k-Nearest Neighbors Algorithm
1.1 Algorithm
The k-nearest neighbors algorithm assumes a training dataset is given in which the class of each instance is known.
For classification, a new instance is predicted from the classes of its k nearest training instances by majority voting or similar rules. Therefore, the k-nearest neighbors method has no explicit learning process.
1.2 Model
Three basic elements: distance measure, k value, and classification decision rule
In general, the feature space is partitioned so that, for each training instance point xi, all points closer to that point than to any other form a cell. Each training instance point has a cell, and every point in the cell is labeled with class yi.
In this way, the class of every point in the feature space is determined.
(1)Distance
The distance between two instance points in the feature space is generally the Euclidean distance, or more generally the distance
When l=2 it is the Euclidean distance, when l=1 it is the Manhattan distance, and when l=∞ it is the maximum of the coordinate-wise distances.
(2)k value
If k is too small, although the prediction may be relatively accurate, the result is overly influenced by neighboring points; if a neighboring point happens to be noise, the prediction will be wrong.
If k is too large, examples farther from the input will also contribute to the prediction.
If k=N, the output is always the most frequent class among the instances.
(3)Classification decision rule
Usually the majority class among the k nearest-neighbor instances.
II. kd-tree
When making predictions, a k-nearest neighbors search is required over the training data. A linear scan would need to compute the distance from the input point to every training instance, which is too slow.
2.1 Constructing a kd-tree
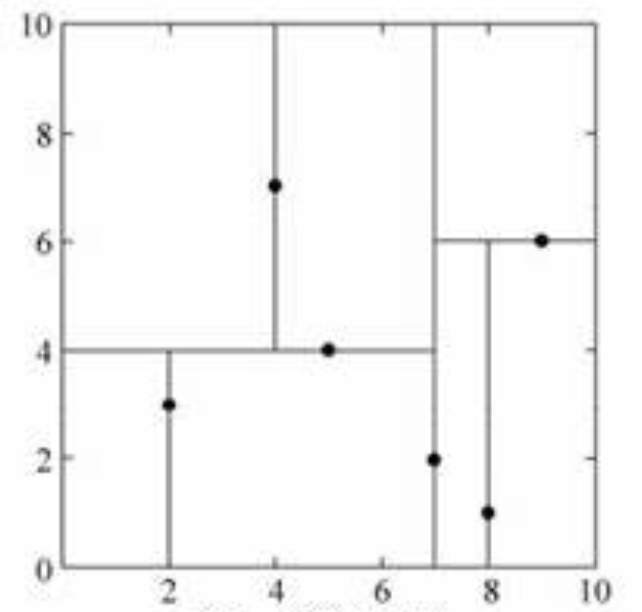
Constructing a kd-tree amounts to repeatedly partitioning k-dimensional space with hyperplanes perpendicular to the coordinate axes; each node corresponds to a k-dimensional hyperrectangle region.
Construction process:
- Construct the root node: the root corresponds to the hyperrectangle region of k-dimensional space that contains all instance points
- Recursive partitioning: in the hyperrectangle region, choose a coordinate axis and a split point on that axis, determine a hyperplane, and use this hyperplane to partition the current hyperrectangle into left and right subregions (child nodes)
- Repeat this process until a subregion contains no instances, at which point it terminates (leaf node)
2.2 Searching a kd-tree
Input: an already constructed kd-tree, target point x Output: the nearest neighbor of x
- Find the leaf node in the kd-tree that contains the target point x: starting from the root, recursively visit the kd-tree downward. If the target point x’s coordinate in the current dimension is less than the split point’s coordinate, move to the left child; otherwise move to the right child. Continue until the child is a leaf. (Somewhat similar to binary search)
- Take this leaf as the “current nearest point”
- Recursively backtrack upward, performing the following at each node:
- If the instance stored at that node is closer to the target than the current nearest point, take that instance as the “current nearest point”.
- The current nearest point must lie in a region corresponding to one child of that node. Check whether the region corresponding to the other child of that child’s parent may contain a closer point. That is, check whether the region corresponding to the other child intersects the hypersphere centered at the target with radius equal to the distance between the target and the “current nearest point”. If they intersect, a point closer to the target may exist in the other child’s region, so move to the other child. Then recursively perform nearest-neighbor search; if they do not intersect, backtrack upward.
- When backtracking reaches the root, the search ends. The final “current nearest point” is the nearest neighbor of x.
Comments