Contents
  1. I. Bayes’ Theorem
  2. 1.1 Conditional Probability
  3. 1.2 Bayes’ Theorem
  4. 1.3 Naive Bayes
  5. II. Posterior Probability Maximization Criterion
  6. III. Maximum Likelihood Estimation

I. Bayes’ Theorem

1.1 Conditional Probability

Conditional probability is a concept in probability theory. It refers to the probability of event B occurring given condition A, denoted by P(B|A), and is calculated as follows.

P(BA)=P(AB)P(A)P(B|A)=\frac{P(AB)}{P(A)}

1.2 Bayes’ Theorem

Compared with conditional probability, Bayes’ theorem applies the inverse process. Given that event B has occurred, it calculates the probability of condition A under which the event occurred, namely P(A|B). It is calculated as follows, where the denominator is the law of total probability.

P(AB)=P(AB)P(B)=P(AB)P(B)P(BA)P(A)+P(BA^)P(A^)P(A|B)=\frac{P(AB)}{P(B)}=\frac{P(A|B)\cdot P(B)}{P(B|A)\cdot P(A)+P(B|\hat A)\cdot P(\hat A)}

Likewise, extending this to a classification problem, suppose there are K classes c1,c2ckc_1,c_2\dots c_k. Given a new instance x=(x(1),x(2)x(n))x=(x^{(1)},x^{(2)}\dots x^{(n)}), we want to determine the likelihood that this instance belongs to class cic_i.

P(Y=ciX=x)=P(X=xY=ci)P(Y=ci)P(X=x)=P(X=xY=ci)P(Y=ci)i=1KP(X=xY=ci)P(Y=ci)P(Y=c_i|X=x)=\frac{P(X=x|Y=c_i)\cdot P(Y=c_i)}{P(X=x)}=\frac{P(X=x|Y=c_i)\cdot P(Y=c_i)}{\sum^K_{i=1}P(X=x|Y=c_i)\cdot P(Y=c_i)}

1.3 Naive Bayes

Compared with the general Bayes approach, naive Bayes adds the assumption that the features of an instance are mutually independent, making the calculation easier.
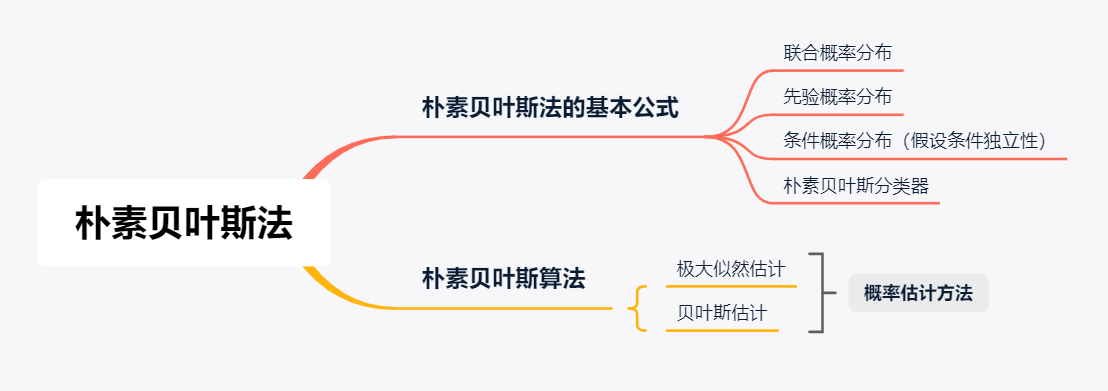
That is, P(X=xY=ci)=j=1nP(X(j)=x(j)Y=ci)P(X=x|Y=c_i)=\prod^n_{j=1}P(X^{(j)}=x^{(j)}|Y=c_i)

Therefore,

P(Y=ciX=x)=P(X=xY=ci)P(Y=ci)ciKP(Y=ci)j=1nP(X(j)=x(j)Y=ci)P(Y=c_i|X=x)=\frac{P(X=x|Y=c_i)\cdot P(Y=c_i)}{\sum^K_{c_i}P(Y=c_i)\prod^n_{j=1}P(X^{(j)}=x^{(j)}|Y=c_i)}

P(Y=ciX=x)=P(Y=ci)j=1nP(X(j)=x(j)Y=ci)ciKP(Y=ci)j=1nP(X(j)=x(j)Y=ci)P(Y=c_i|X=x)=\frac{P(Y=c_i)\cdot \prod^n_{j=1}P(X^{(j)}=x^{(j)}|Y=c_i)}{\sum^K_{c_i}P(Y=c_i)\prod^n_{j=1}P(X^{(j)}=x^{(j)}|Y=c_i)}

The denominator is the same for the probability that xx belongs to any class cic_i. Therefore, in practice, only the numerators need to be compared:

argmaxP(Y=ci)j=1nP(X(j)=x(j)Y=ci)argmax P(Y=c_i)\cdot \prod^n_{j=1}P(X^{(j)}=x^{(j)}|Y=c_i)

The joint probability distribution can be obtained from the training dataset.

II. Posterior Probability Maximization Criterion

III. Maximum Likelihood Estimation