Contents
- Version Issues
- 1. Model Weights Trained with Different Versions of PyTorch Cannot Be Loaded.
- 2. ValueError: numpy.ufunc size changed, may indicate binary incompatibility.
- 3. maskrcnn Training Reports: FutureWarning: Input image dtype is bool
- 4. CUDA Version Mismatch
- Environment Configuration/Package Installation
- 1. No module named ‘pycocotools‘
- 2. Successfully Resolved AttributeError: ‘str‘ object has no attribute ‘decode‘
- 3. Switching TensorFlow to Version 1.x When Using Google Colab
- 4. Stuck for a Long Time at Successfully opened dynamic library libcudnn.so.7
- 5. pip Package Installation Errors
- Data Format Mismatch
- 1. TypeError: expected str, bytes or os.PathLike object, not NoneType
- Multi-GPU Issues
- 1. ValueError: Memory growth cannot differ between GPU devices
It is recommended to press Ctrl+F and enter keywords to see whether this page contains the bug you encountered. Alternatively, check the table of contents on the left.
All the problems and solutions below are ones I personally encountered and successfully resolved using these methods. If you still have problems, feel free to discuss them in the comments.
Version Issues
1. Model Weights Trained with Different Versions of PyTorch Cannot Be Loaded.
pickle.UnpicklingError: A load persistent id instruction was encountered, but no persistent_load function was specified.
Cause: The torch versions used for training and testing are inconsistent. Training used 1.x, while testing used 1.m.
Solution: First load the model under version 1.x, then set _use_new_zipfile_serialization=False when saving it.
torch.save(model.state_dict(), model_path, use_new_zipfile_serialization=False)2. ValueError: numpy.ufunc size changed, may indicate binary incompatibility.
This is caused by an outdated NumPy version. Upgrade NumPy to resolve it.
pip uninstall numpy
pip install numpy
pip install --upgrade numpy
3. maskrcnn Training Reports: FutureWarning: Input image dtype is bool
Reference blog: https://blog.csdn.net/qq_39483453/article/details/118598535
This issue exists in scikit-image=0.17.2. Change the scikit-image package version to 0.16.2.
pip install -U scikit-image==0.16.24. CUDA Version Mismatch
Error log: The detected CUDA version (12.1) mismatches the version that was used to compile PyTorch (11.3). Please make sure to use the same CUDA versions.
Solution: Install multiple versions of CUDA.
(1) Download CUDA
Go to the official website, then download and install an older version of CUDA.
wget https://developer.download.nvidia.com/compute/cuda/11.3.0/local_installers/cuda_11.3.0_465.19.01_linux.run
sudo sh cuda_11.3.0_465.19.01_linux.run
Deselect CUDA Driver installation.
Do you want to install a symbolic link at /usr/local/cuda? # Whether to link the installation directory to /usr/local/cuda via a symbolic link
Select yes.
(2) Switching Between Multiple Versions
Modify the CUDA path in ~/.bashrc: open ~/.bashrc and add the following at the end (change the version number to the required CUDA version):
export PATH="/usr/local/cuda-10.2/bin:$PATH"
export LD_LIBRARY_PATH="/usr/lcoal/cuda-10.2/lib64:$LD_LIBRARY_PATH"
Use source ~/.bashrc to update the configuration.
Use nvcc --version to check. If it shows the CUDA version you just installed, the installation was successful.
Environment Configuration/Package Installation
1. No module named ‘pycocotools‘
Reference blog: A Super-Simple Fix for No module named ‘pycocotools‘
pycocotools.whl Files for Each Version
Click any version at the link (I installed 2.0.0). When downloading, be sure to choose the version matching your python version: cp36 refers to python3.6, and the same applies to cp37 and cp38.
After downloading, place it in any folder you like. Then open a command line, go to the directory containing the whl file, and enter the following command. Note that the text after install must be the full name of the whl file you downloaded.
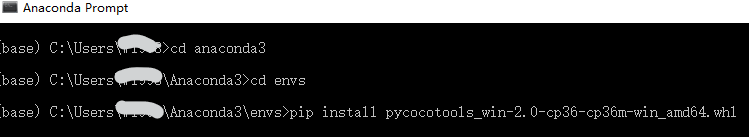
activate tensorflow
E:
cd E:/windows/Downloads
pip install pycocotools_windows-2.0-cp36-cp36m-win_amd64.whl
2. Successfully Resolved AttributeError: ‘str‘ object has no attribute ‘decode‘
Reference blog: https://blog.csdn.net/qq_41185868/article/details/82079079
pip install 'h5py<3.0.0' -i https://pypi.tuna.tsinghua.edu.cn/simple3. Switching TensorFlow to Version 1.x When Using Google Colab
Reference blog: https://blog.csdn.net/qq_44262417/article/details/105222696
%tensorflow_version 1.x4. Stuck for a Long Time at Successfully opened dynamic library libcudnn.so.7
The cause is a mismatch between the tensorflow and CUDA versions. I was using cuda11.6 and tensorflow2.2.0.
After researching the issue, viable combinations include CUDA11.2+Tensorflow2.5.0.
5. pip Package Installation Errors
Error 1: ImportError: No module named pip._internal.cli.main
Error log:
Traceback (most recent call last):
  File "/home/mahaofei/anaconda3/envs/linemod/bin/pip", line 6, in <module>
    from pip._internal.cli.main import main
ImportError: No module named pip._internal.cli.main
Solution:
The pip version installed in the python2.7 environment is too old to install many packages properly.
python -m ensurepip
pip install --upgrade pip
Error 2: Could not find a version that satisfies the requirement
Error log:
ERROR: Could not find a version that satisfies the requirement comm>=0.1.3 (from ipywidgets) (from versions: 0.0.1)
ERROR: No matching distribution found for comm>=0.1.3 (from ipywidgets)
Solution:
pip install package -i https://pypi.tuna.tsinghua.edu.cn/simpleIf ipywidgets cannot be installed with pip, use:
conda install -c conda-forge ipywidgetsData Format Mismatch
1. TypeError: expected str, bytes or os.PathLike object, not NoneType
This problem is usually caused by not specifying a path. The error means that a string or byte path is expected rather than a default value. To resolve it, assign a value to the variable that specifies the path. This error often occurs when running open-source code.
Check whether the string variable at the corresponding location in the code has a definite value rather than None.
Multi-GPU Issues
1. ValueError: Memory growth cannot differ between GPU devices
This is a multi-GPU issue. All GPUs are used by default during computation, but set_memory_growth is configured for only some of them, causing a mismatch between GPU modes. A simple solution is to add the following before the code that reports the error:
os.environ['CUDA_VISIBLE_DEVICES']='0'One important point is that a setting such as os.environ[‘CUDA_VISIBLE_DEVICES’]=‘0’ must be declared before calling the TensorFlow framework; otherwise, it will not take effect.
Comments